Deep Analysis Schedule
7 published batches
Daily, weekly and deep-analysis updates
Different updates, different clocks. Follow daily market rankings, weekly editorial reviews, deep-analysis runs and published research, with a record of what we learned along the way.
Deep Analysis
Bi-Monthly Every two months · target cadence
Deep analysis refreshes the underlying research, assumptions and forecast scenarios. It runs in discrete batches, separately from daily price-based rescoring and weekly editorial review. Planned windows and all published runs are recorded below.
From evidence to a published research record
The Investment Relations workflow- 01
Data and context
Prices, filings, news, and company and macro context.
426 assets in the latest published batch - 02
Deep Analysis by AI Analysts
Independent perspectives across investing frameworks, models and tools.
5,964 individual reports across the entire 426-asset universe in the latest published batch
- 03
AI synthesizer
Normalize and score each asset’s individual reports, then assign its final consensus rating and forecast path.
Consensus and second-stage synthesis - 04
Forecasts released
Publish theses, risks, scenarios and dated price paths readers can revisit.
Consensus and individual reports - 05
Live Rankings
Our research-backed scoring formulas compare and rank assets against one another.
One comparable research universe - 06
Editorial Top Picks
Review candidates in greater depth to confirm top picks by category.
Category-level AI confirmation
Live Rankings
Daily Around 04:10 UTC
Rankings are refreshed against the latest available market prices. Expected returns and relative ranks can change while the underlying deep-analysis forecasts stay the same.
Updated rankings appear after processing and publication complete; market data availability can affect timing.
Open Live RankingsEditorial Picks
Weekly Usually Fridays
We review the evidence behind the category selections, including changes in valuation, the investment thesis and the risks worth watching.
Friday is the usual review cadence. Selections are published after review; a weekly review does not imply a new deep-analysis batch.
Explore Editorial PicksDeep Research Schedule
| Research batch | Status | Run date | Assets analyzed | Model Families | Research record |
|---|---|---|---|---|---|
| Batch 8 | Planned | –Estimated · Saturday–Monday | To be confirmed | To be confirmed | Not yet published |
| Batch 7 | Published | 426 | Gemini 3.8 Flash, Claude Opus 5 and GPT-6 Astra | Compare methods | |
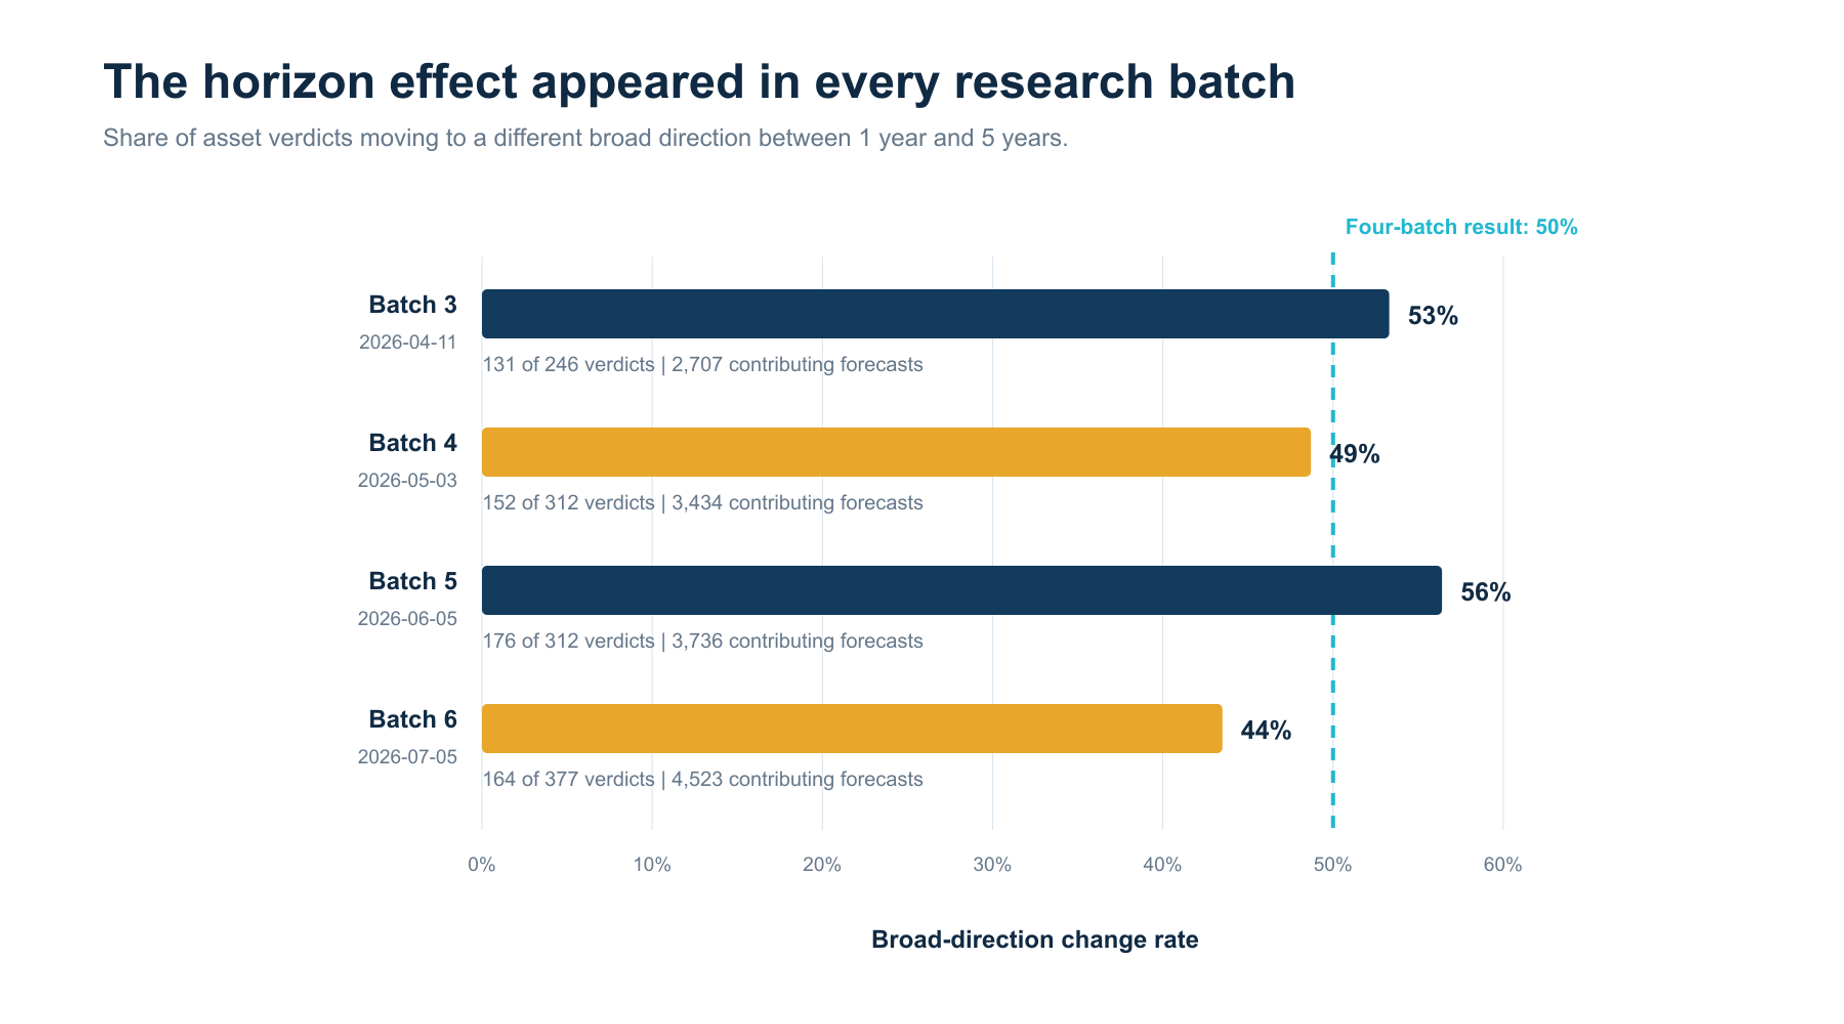
| Batch 6 | Published | 373 | Gemini 3.1 preview configurations | Compare methods | |
| Batch 5 | Published | 312 | Gemini 3.1 preview configurations | Compare methods | |
| Batch 4 | Published | 312 | Gemini 3 Pro preview configurations | Compare methods | |
| Batch 3 | Published | 246 | Gemini 3 Pro preview configurations | Compare methods | |
| Batch 2 | Published | 209 | Gemini 3 Pro preview | Compare methods | |
| Batch 1 | Published | 203 | Gemini 2.5 GA and Gemini 3 preview configurations | Compare methods |
The planned window is an estimate; timing, models and coverage may change. Published dates describe completed research runs. Portfolio execution dates and simulated results follow their own published records. Inspect performance and the trade ledger.
Compare the research batches
The same published comparison as Performance: models, inputs, synthesis, capabilities and improvements across all published batches.
How the research evolved
Models, synthesis and research capabilities · latest batch first| At a glance | Batch 7LatestV7 · 21 Sept 2026 | Batch 6V6 · 5 Jul 2026 | Batch 5V5 · 3 Jun 2026 |
|---|---|---|---|
| Assets in the run | 426 | 373 | 312 |
| Model family | Gemini 3.8 Flash, Claude Opus 5 and GPT-6 Astra | Gemini 3.1 preview configurations | Gemini 3.1 preview configurations |
| Research capability depthDocumented layers, not model IQ | 5 / 5 capabilities | 4 / 5 capabilities | 4 / 5 capabilities |
| Consensus synthesis | Evidence-weighted | Equal-weight | Equal-weight |
Explore the full comparisonAll 7 batches · research inputs, models and improvements
| Research input | Batch 7LatestV7 · 21 Sept 2026 | Batch 6V6 · 5 Jul 2026 | Batch 5V5 · 3 Jun 2026 | Batch 4V4 · 3 May 2026 | Batch 3V3 · 11 Apr 2026 | Batch 2V2 · 19 Mar 2026 | Batch 1V1 · 28 Nov 2025 |
|---|---|---|---|---|---|---|---|
| Assets in the run | 426Analyzed assets | 373Analyzed assets | 312Analyzed assets | 312Analyzed assets | 246Analyzed assets | 209Analyzed assets | 203Analyzed assets |
| Model family | Gemini 3.8 Flash, Claude Opus 5 and GPT-6 Astra | Gemini 3.1 preview configurations | Gemini 3.1 preview configurations | Gemini 3 Pro preview configurations | Gemini 3 Pro preview configurations | Gemini 3 Pro preview | Gemini 2.5 GA and Gemini 3 preview configurations |
| Opinions per assetOriginal 1-year ranking inputs | 14Includes advisor modes and configurations | 12Intended advisor modes and configurationsDetails12 opinions intended per asset; a few assets have 11 completed opinions because one output is missing. | 12Intended advisor modes and configurationsDetails12 opinions intended per asset; a few assets have 11 completed opinions because one output is missing. | 10–12Includes advisor modes and configurations | 10–12Includes advisor modes and configurations | 4–16Includes advisor modes and configurations | 10–12Includes advisor modes and configurations |
| Research capability depthDocumented layers, not model IQ | 5 / 5 capabilities | 4 / 5 capabilities | 4 / 5 capabilities | 2 / 5 capabilities | 2 / 5 capabilities | 1 / 5 capabilities | 1 / 5 capabilities |
| Portfolio status | Trades availableSimulated activity · inspect the ledger below | Trades availableSimulated activity · inspect the ledger below | Trades availableSimulated activity · inspect the ledger below | Trades availableSimulated activity · inspect the ledger below | Trades availableSimulated activity · inspect the ledger below | Trades availableSimulated activity · inspect the ledger below | Trades availableSimulated activity · inspect the ledger below |
| Global contextEvents between the model’s knowledge cutoff and the forecast run date | YesDetailsCombined context coverage: 1 Jan 2025 – 20 Sept 2026.Governed world-state context accompanies the individual forecasts. | YesDetailsCombined context coverage: 1 Jan 2025 – 31 May 2026.Governed global context was supplied. | YesDetailsCombined context coverage: 1 Jan 2025 – 10 Apr 2026.Governed world-state context was included. | YesDetailsCombined context coverage: 1 Jan 2025 – 10 Apr 2026.Governed global context was included in the run. | YesDetailsCombined context coverage: 1 Jan 2025 – 10 Apr 2026.Verified 2025–2026 world-state context was supplied. This is the first batch for which that claim is valid. | NoDetailsBatch 2 did not receive the later world-state context files. | NoDetailsNo global-context component was supplied to Batch 1. |
| Asset fundamentalsEarnings reports, balance sheets and key financial ratios | Equities onlyDetailsCurrency-normalized fundamentals for eligible equities. | Equities onlyDetailsCurrency-normalized fundamentals were supplied for eligible equities. | Equities onlyDetailsAsset-specific fundamentals were introduced for equities, not for asset classes without company financial statements. | NoDetailsAsset-specific fundamentals were not yet part of the run. | NoDetailsAsset-specific fundamentals were not yet part of the run. | NoDetailsNo governed fundamentals input was supplied. | NoDetailsNo governed fundamentals input was supplied. |
| Cross-asset rankings | YesDetailsPortfolio simulations use the frozen original quantitative leaderboard, separate from the synthesized forecast path. | YesDetailsCurrent v7.4 architecture adds event-risk pressure and equity financial health; historical snapshots retain their formula identifiers. | YesDetailsThe v7.2/v7.3 ranking generation incorporated dividend, dispersion, volatility, and cash-hurdle logic. | YesDetailsRankings used the then-current post-generation formula and were later eligible for reproducible re-scoring. | YesDetailsPost-generation ranking work existed, with formulas continuing to evolve after the run. | Added laterDetailsThe first ranking implementation was created after this run, beginning March 27, 2026. | Added laterDetailsRanking did not exist at generation time; frozen forecasts were eligible for later retrospective scoring. |
| Consensus synthesis | Evidence-weightedIntelligence layer · explained, adjustable opinion weightsDetailsThe synthesizer assigns explained per-opinion weights; Python calculates and compounds the weighted quarterly returns. | Equal-weightSimple averaging · every opinion counts equallyDetailsIndependent forecasts were synthesized into asset-level consensus records. | Equal-weightSimple averaging · every opinion counts equallyDetailsA second batch layer combined independent advisor forecasts into an asset consensus. | NoDetailsThe dedicated asset-consensus layer followed this batch. | NoDetailsThe dedicated asset-consensus layer had not yet been introduced. | NoDetailsThe asset-consensus layer had not yet been introduced. | NoDetailsForecasts were produced independently without the later asset-consensus layer. |
| Editorial review | YesDetailsSeparate editorial publication approval remains downstream of forecasts and rankings. | Added laterDetailsThe formal editorial-review workflow was added after Batch 6 generation and now governs publication of Editorial Top Picks. | NoDetailsThe formal editorial stage was introduced after the next deep-analysis execution. | NoDetailsThe editorial publication workflow did not yet exist. | NoDetailsThe editorial publication workflow did not yet exist. | NoDetailsThe editorial publication workflow did not yet exist. | NoDetailsThe editorial publication workflow did not yet exist. |
| Model diversity comparison | YesDetailsMatched Universal Investor researcher configuration across Flash, Opus and Astra; each asset has 12 Flash, one Opus and one Astra opinion. | NoDetailsThis batch predates the matched three-model comparison. | NoDetailsThis batch predates the matched three-model comparison. | NoDetailsThis batch predates the matched three-model comparison. | NoDetailsThis batch predates the matched three-model comparison. | NoDetailsThis batch predates the matched three-model comparison. | NoDetailsThis batch predates the matched three-model comparison. |
| Evidence-based opinion weighting | YesDetailsBlinded opinion identities support lower or zero weights for weak claims and higher weights for supported insights. Weights are normalized and the complete source path is frozen. | NoDetailsNo Batch 7 per-opinion judgment allocations were applied. | NoDetailsNo Batch 7 per-opinion judgment allocations were applied. | NoDetailsNo Batch 7 per-opinion judgment allocations were applied. | NoDetailsNo Batch 7 per-opinion judgment allocations were applied. | NoDetailsNo Batch 7 per-opinion judgment allocations were applied. | NoDetailsNo Batch 7 per-opinion judgment allocations were applied. |
| What changed | 3 improvements
| 2 improvements
| 4 improvements
| 2 improvements
| 3 improvements
| 3 improvements
| 2 improvements
|
How the five-brain scale works: one point each for independent forecasts, global context, equity fundamentals, consensus synthesis and evidence-based opinion weighting. Partial equity coverage counts; features added after a run do not. This is a capability checklist—not measured intelligence, accuracy or investment performance.
Batch 7 adds matched Flash, Opus and Astra comparisons and explained synthesizer weights. Earlier synthesis used equal opinion weights. These are research methods, not evidence of improved accuracy. Portfolio simulations still use frozen quantitative rankings, separate from the synthesized forecast path. Engine history Lessons learned
Lessons Learned
Loading the public lessons ledger…
Research Articles Schedule
Loading the published research catalog…